Edit with references
Your photo, dressed by other photos — jacket from one, sunglasses from another, puppy from a third.
MiniMax H3-Image takes the main photo plus up to three reference pictures and one instruction that names each picture — Picture 1 is the main photo, Picture 2 the outfit, Picture 3 the accessory, Picture 4 the companion — and fuses them positionally into a single scene. A Gemini survey writes the subject's anchors first; a blind Gemini re-read describes the result; a GLM checker grades whether every piece landed and the subject survived.
Saved result
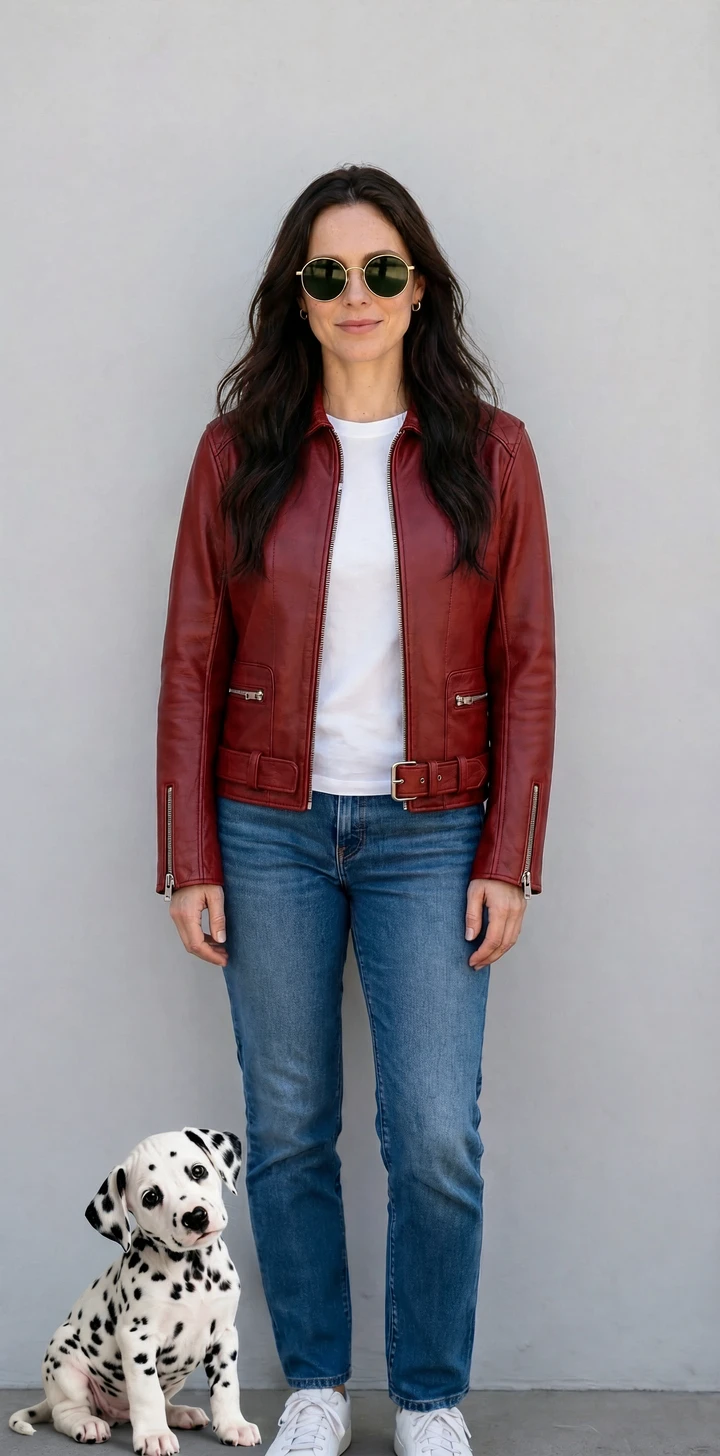
Subject anchors · Gemini reads the main photo · reported $0.0029
Face: Oval face, fair skin with light freckles, dark brown eyes, small hoop earrings. Hair: Dark brown, chest-length, parted in the middle with loose waves. Outfit now: Plain white crewneck short-sleeve t-shirt, blue straight-leg denim jeans, white sneakers. Pose: Standing upright facing forward, arms hanging straight down at the sides, legs straight. Background: Solid flat light grey wall behind, smooth grey concrete ground underfoot.
Blind re-read · Gemini describes the result · reported $0.0036
Person: A woman with long, wavy dark brown hair parted in the middle, looking forward with a slight smile. Wearing: A red leather jacket, a plain white crewneck t-shirt, blue straight-leg jeans, and white sneakers. Accessories: Round dark sunglasses with thin metallic frames and small metallic hoop earrings. Animals: A Dalmatian puppy with white fur and black spots, sitting on the ground to the woman's lower-left side. Background: A plain, flat light gray wall and a smooth gray floor.
Edit report · GLM grades the fusion · reported $0.00
LANDED: red leather jacket, white t-shirt, jeans and sneakers unchanged, Dalmatian puppy sitting on the floor beside the legs, plain grey wall and floor preserved, hoops earrings preserved, long dark hair and pose preserved MISSING: jacket worn open (unclear in the re-read), round gold-framed sunglasses (re-read says only thin metallic frames, color unclear), puppy looking at the camera (unclear in the re-read) SUBJECT: SURVIVED — face, hair, outfit, pose, and background all match the anchors with no drift.
References that went in
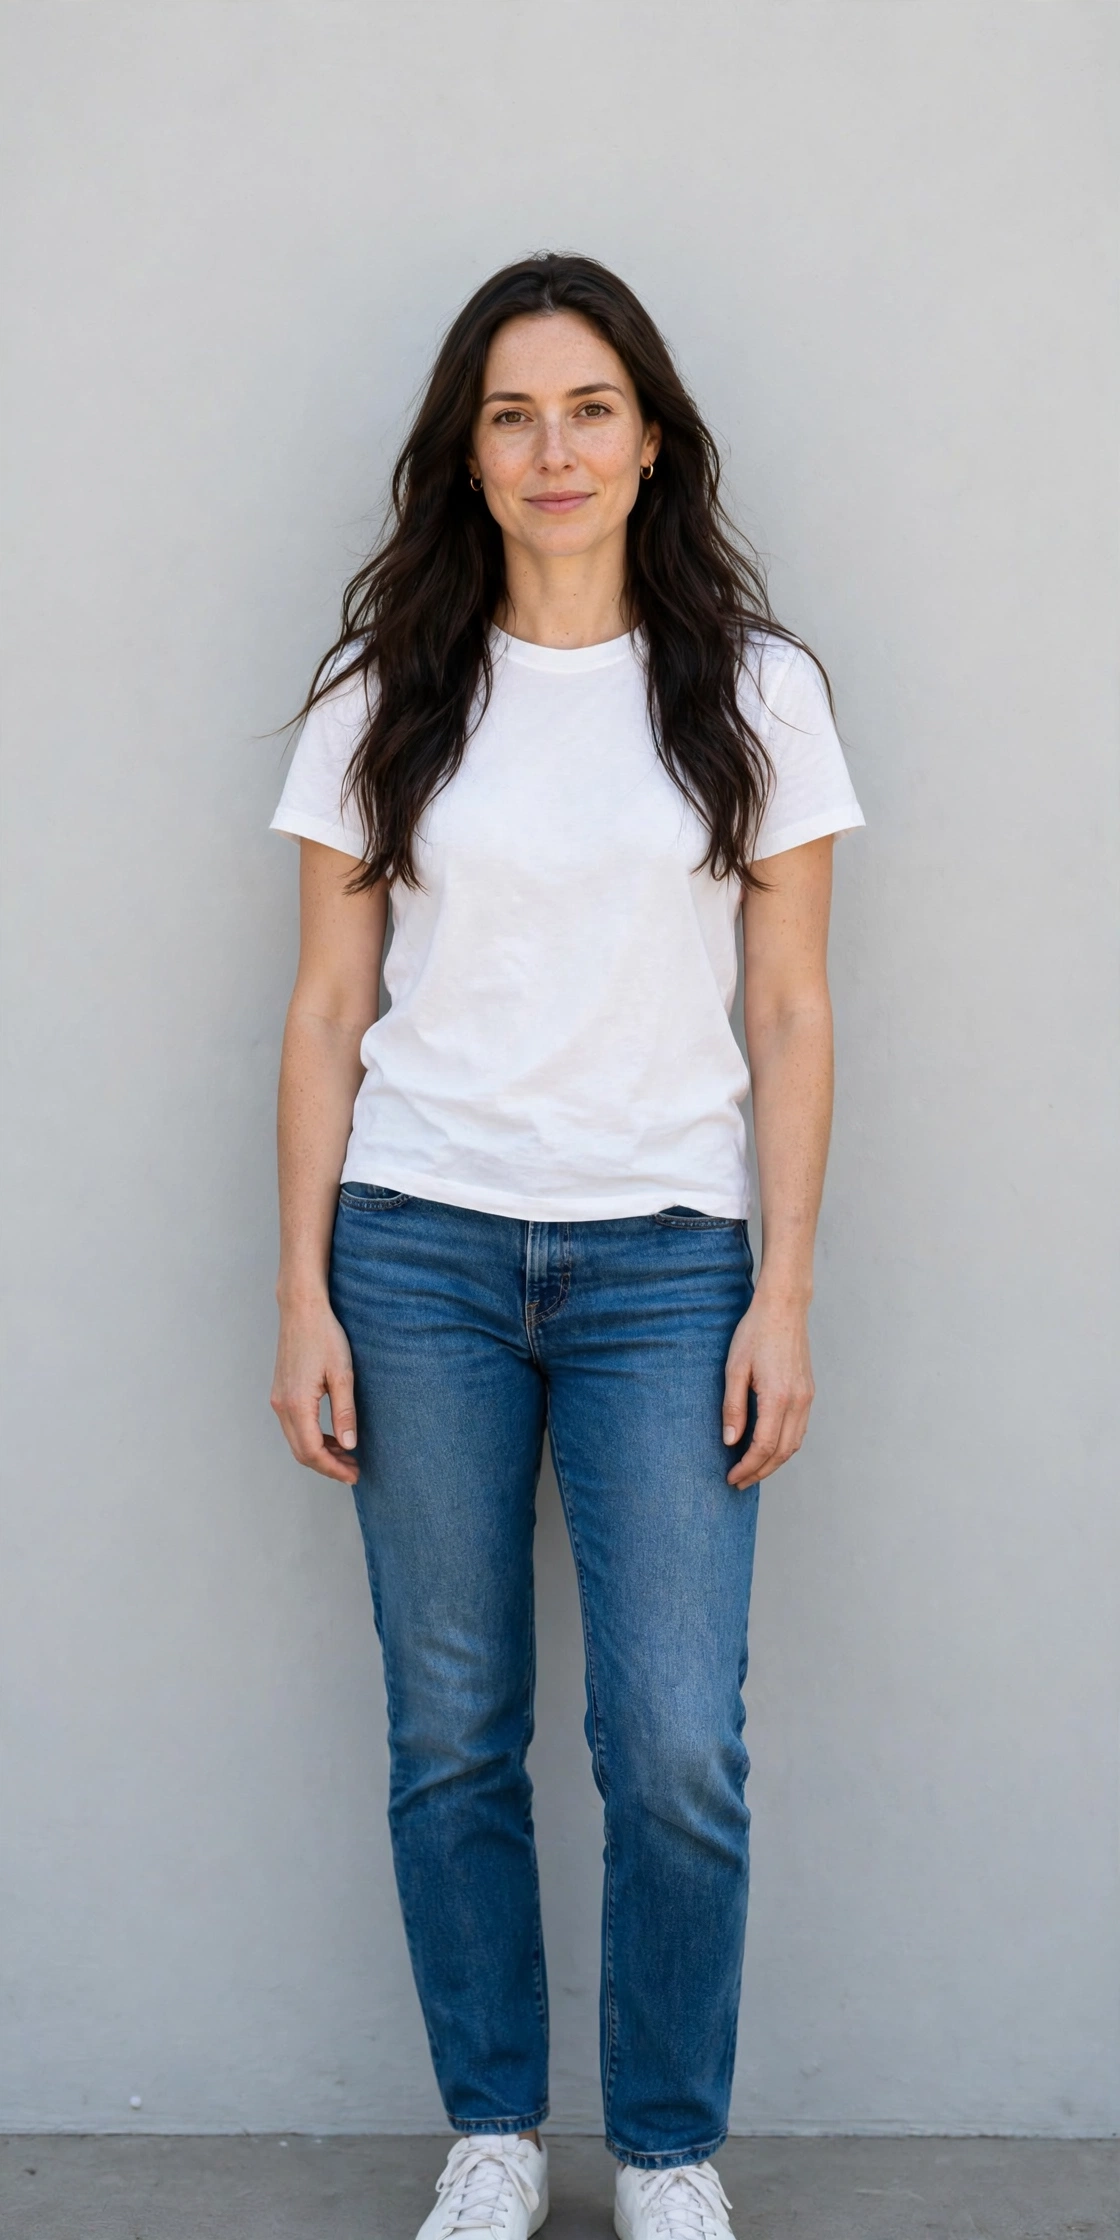
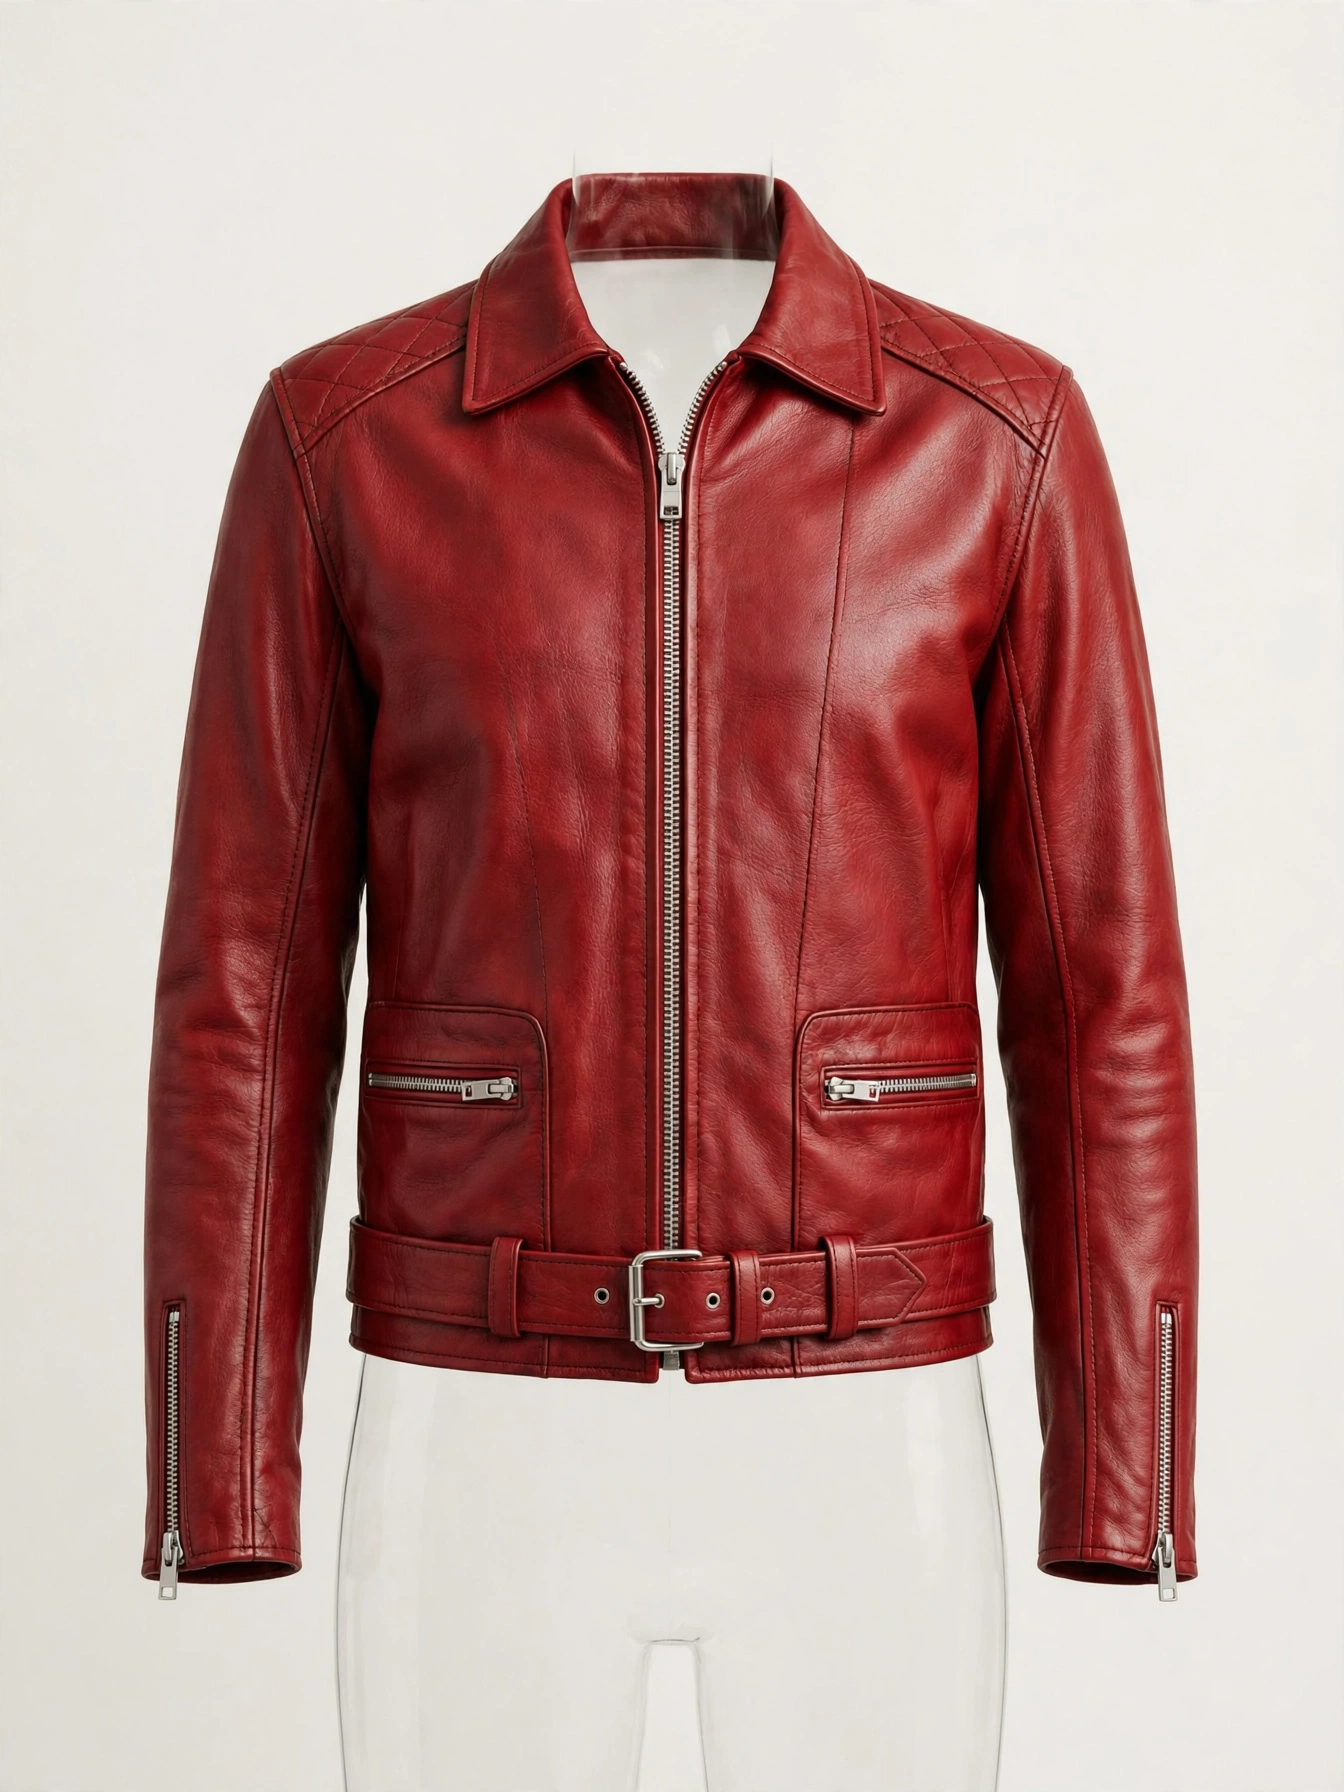
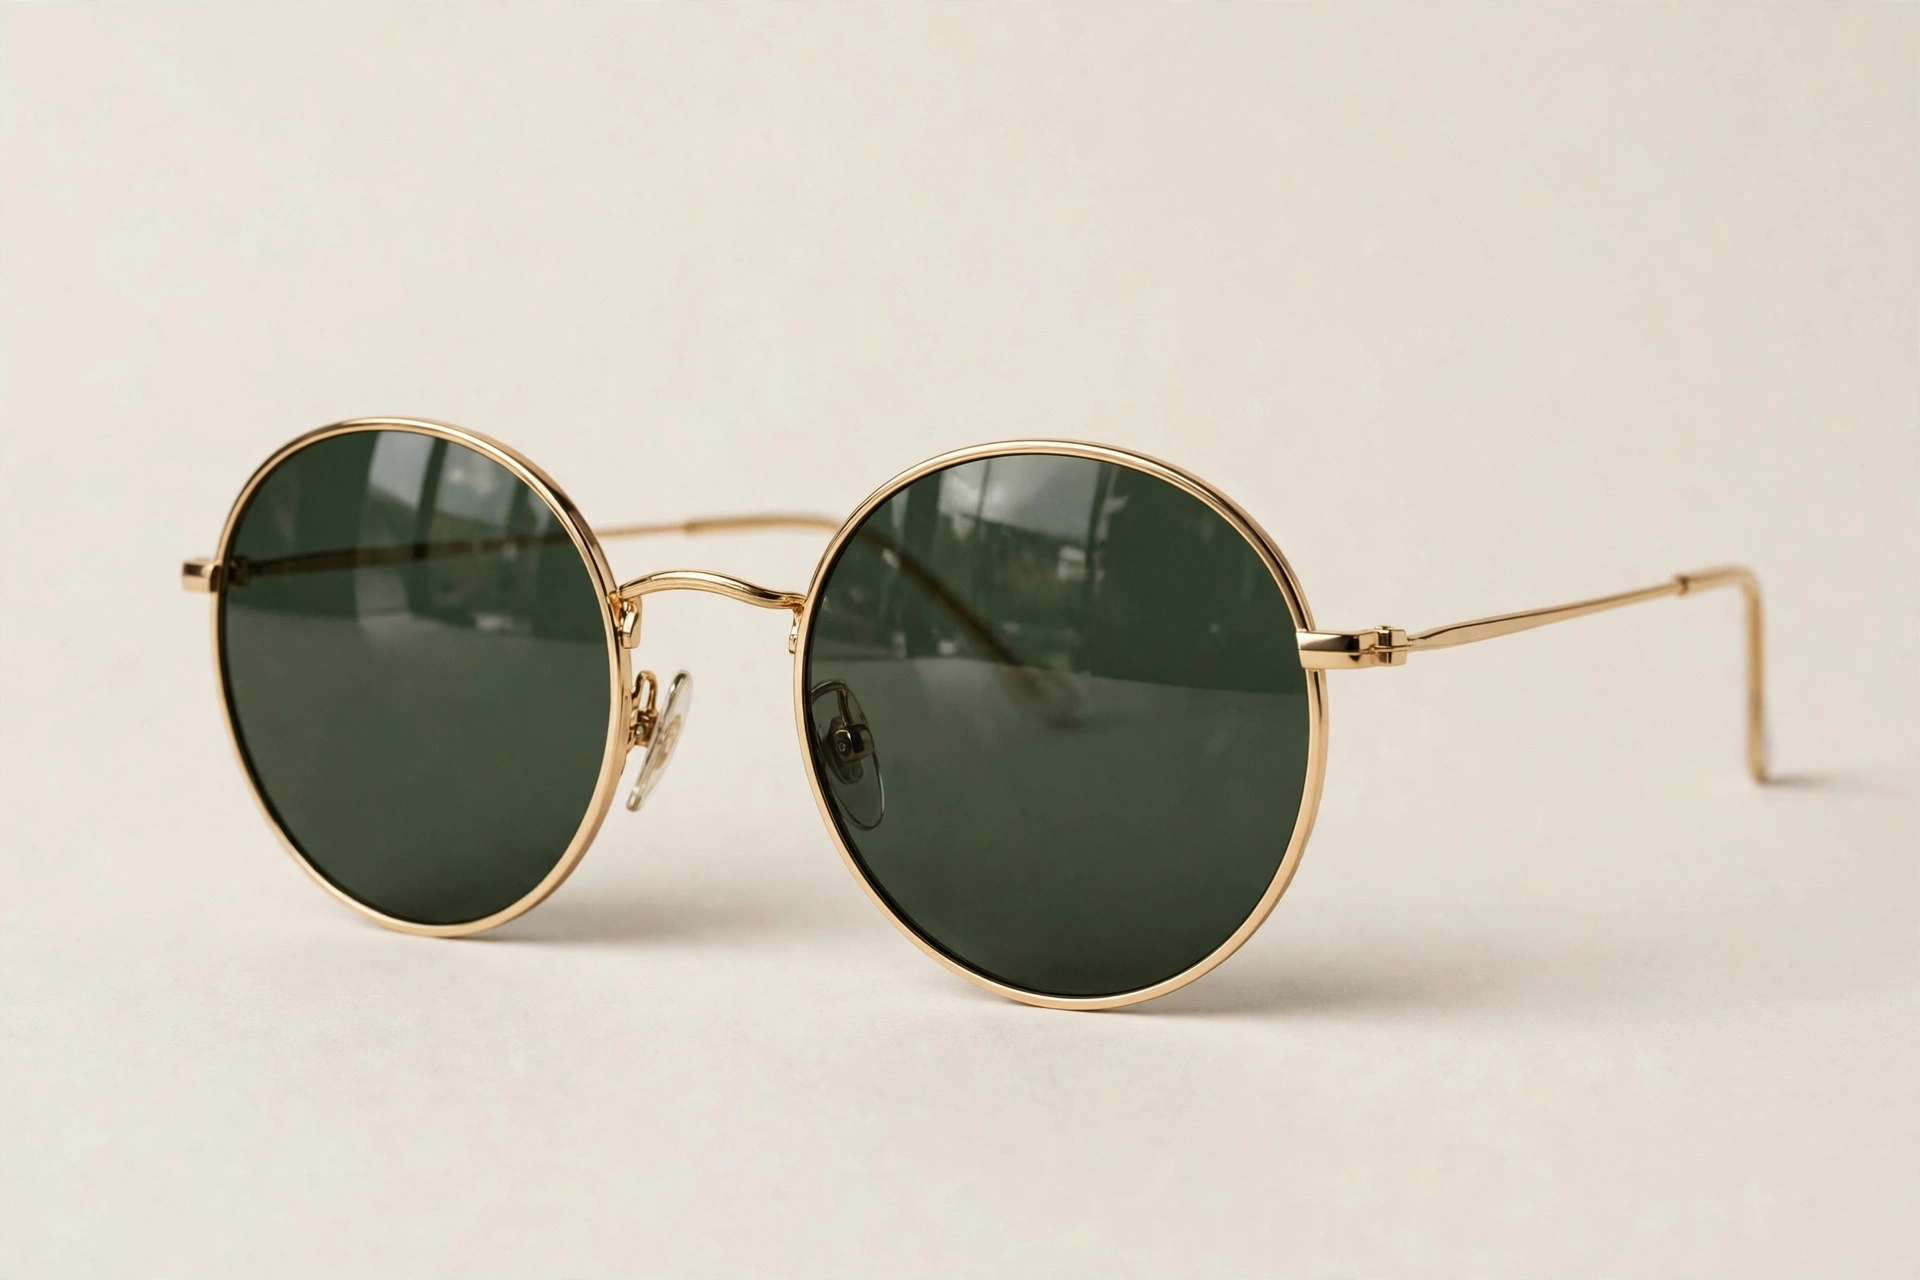
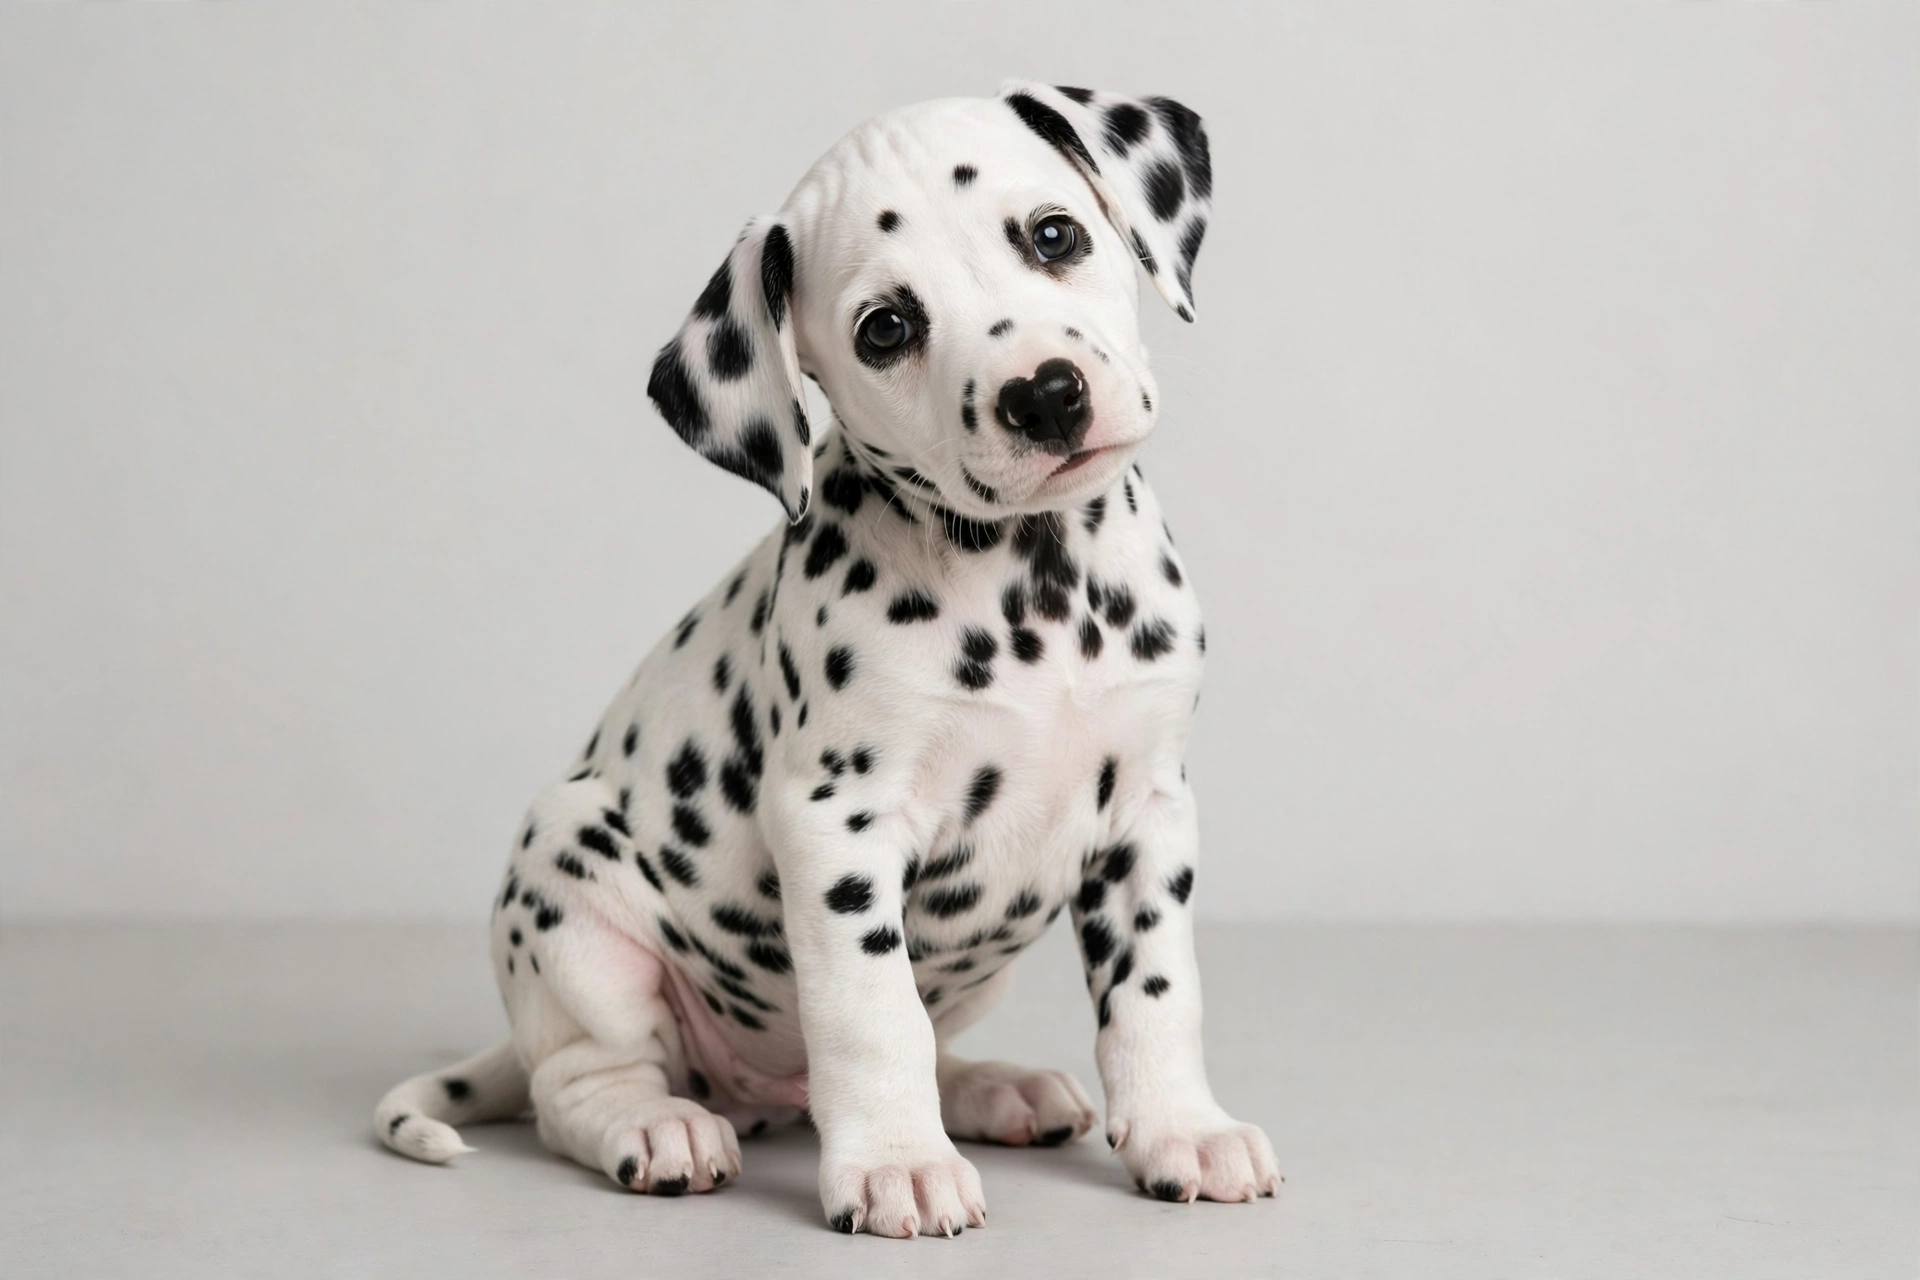
Upload one main photo and up to three reference pictures, then write one instruction that names each picture — Picture 1 is the main photo, Picture 2 the outfit, Picture 3 the accessory, Picture 4 the companion — and MiniMax H3-Image fuses them positionally into a single scene. It takes up to sixteen references this way. Before the edit, a Gemini survey writes the subject's anchors (face, hair, outfit, pose, background); after it, a second Gemini re-reads the result blind, never having seen the originals; a GLM checker holds instruction, anchors and re-read against each other and prints LANDED, MISSING and whether the SUBJECT SURVIVED. Why this model: H3-Image held #1 on Hugging Face trending for six straight days in November 2026 (~3.4M downloads) and tops independent open-weights editing boards, but its open weights total ~135 GB and the MiniMax community license excludes the US, EU, UK and Korea — most of the people downloading it cannot run it locally, so hosted in a browser is the route. In the saved run all four pictures land: the jacket is on her, worn open over the white t-shirt with its belt and zip pockets carried over; the sunglasses are on her face; the puppy sits by her legs with its head tilt intact; face, hair, pose, jeans and the grey wall are unchanged. Flaws and limits, honestly: the checker graded the sunglasses and the open jacket 'unclear in the re-read' — the blind reader hedged on fine detail that is plainly visible in the picture itself, because the audit grades from text, not pixels; that conservatism is the design, but it means a clean edit can still print MISSING lines. The puppy's gaze lands near the camera rather than straight into it. The edit node's size is pinned to 1k — H3 accepts only 1K or 2K output and rejects pixel sizes, a pin found by a failed first probe. The four demo photos were painted by the media pipeline because the flow takes any upload — swap in real photos and it runs as saved.
Make it yours
- Open the graph — save first if the canvas already has your work. Undo brings yours back.
- Swap Main photo for your own portrait and Reference 1 · outfit, Reference 2 · accessory and Reference 3 · companion for your own garment, accessory and companion shots — keep the picture numbering, and rewrite Edit instruction (names each picture) to match. Keep Fuse the references on
minimax-h3-imageat size1k— H3 accepts only 1K or 2K output and rejects pixel sizes. The model takes up to 16 references if you wire more 📷 inputs. - Check the editor estimate, then run with your NanoGPT key. Four model calls: the saved run reported $0.0705 in total (H3-Image edit $0.064 with three references, Gemini anchors $0.0029, blind re-read $0.0036, GLM checker $0.00). Prices and results vary.
- Compare the fused scene with the four inputs one at a time: is the garment the one from its reference, is the subject still the same person, did anything uninvited move in? Then read the Edit report. LANDED and MISSING are graded from the blind re-read's text, not the pixels — in the saved run the checker hedged the sunglasses and the open jacket as unclear while both sit plainly in the picture. That conservatism is the audit working as designed.
edit-with-references.NOTE.txt
Download workflow · Original sampled graph · Explore MCP tools · awesome-noodles