Three references, one clip
Put a specific character, prop and place into one video clip and keep all three looking like your references.
Show reference-to-video: instead of starting from one first frame, the Text→Video node takes several reference images on its ref ports and the model builds a new shot that contains all of them, so one character design can be reused across many different shots.
Saved result
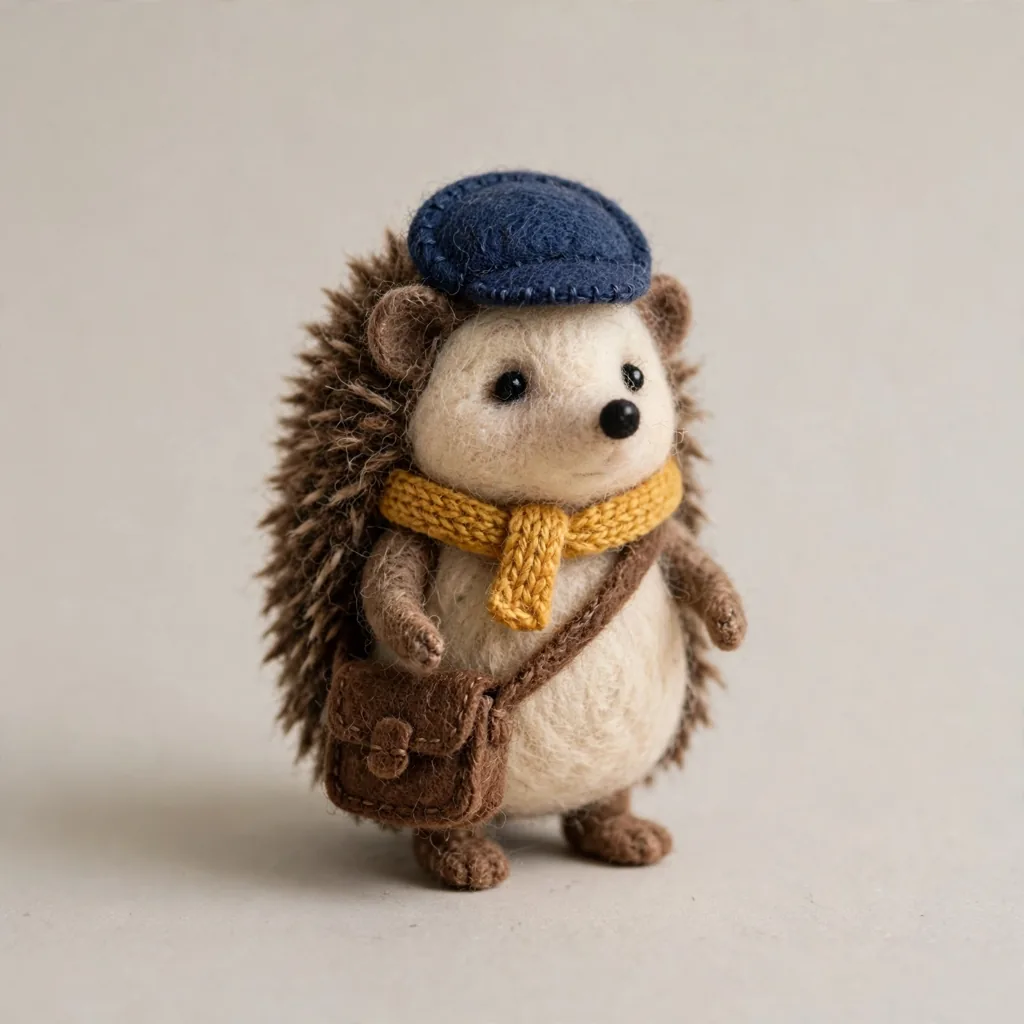
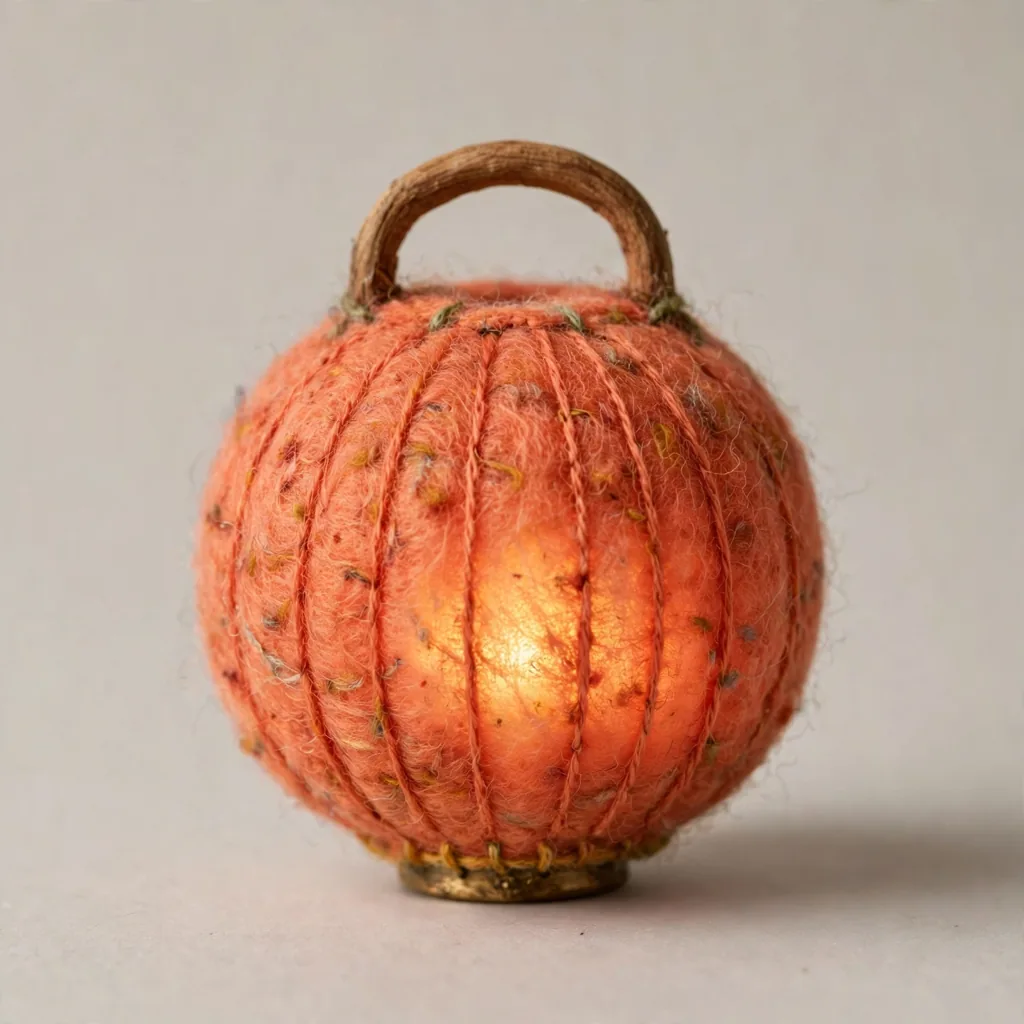
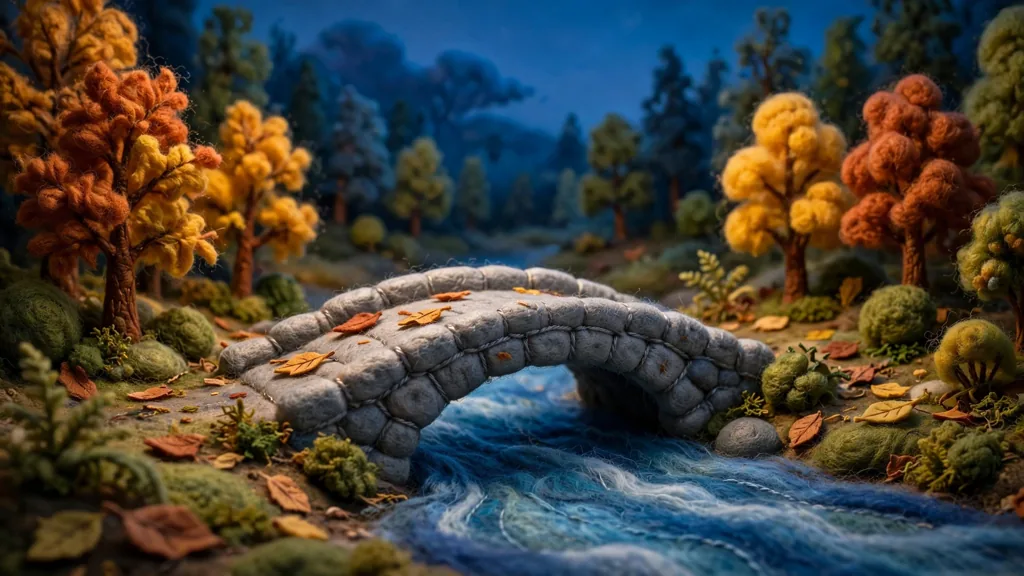
Muse paints three separate reference stills, all in one needle-felted wool stop-motion look: a little hedgehog mail carrier (brown felted spines, mustard knitted scarf, navy cap, brown satchel), a coral-orange ribbed paper lantern with a wooden handle, and an empty grey stone arch bridge over a blue wool stream in an autumn felt forest at dusk. All three go into one Text→Video node on its ref1, ref2 and ref3 ports, and MiniMax H3 Reference-to-Video (540p, 5 s) films one shot with them: the hedgehog walks onto the left end of the bridge carrying the unlit lantern by its handle while the camera tracks to the right past the felt trees, and at about 3.5 s the lantern lights up with a warm candle glow that he holds up. The character keeps its cap, scarf, satchel and face, the lantern keeps its shape, color and handle, and the bridge, stream and trees match the place still. This is the video version of Mix the references, which only makes a still. Flaws: the model ignored the framing in the prompt. Instead of crossing to the middle of the bridge, the hedgehog stays pinned to the left edge while the camera pans away, so he is cut off by the frame edge in the first half-second and again at the end. The glow lights the ground near him rather than the whole bridge, and the stream drifts out of frame as the camera pans. A retake with a locked-off-camera prompt panned the same way and kept him even smaller, so the first take is the one shown. The clip has its own generated sound (soft footsteps, then a rising tone as the lantern lights; no voice). Swap any Image node for a 📷 Image input to use your own references. Every still and sampled video frame was checked and is SFW (a felt cartoon hedgehog, a lantern and a forest; no people, no logos). Inspired by @ComfyUI's FastH3 OmniRef multi-reference video post (https://x.com/ComfyUI/status/2112645504769413283) and @OrctonAI's reference-character video tests (https://x.com/OrctonAI/status/2112955932216791381). No media from those posts is used.
Make it yours
- Open the graph — save first if the canvas already has your work. Undo brings yours back.
- Rewrite Ref 1 · character, Ref 2 · prop and Ref 3 · place for your own subjects, keeping the same "Look:" line at the start of each so they share one style, or swap any Image node for a 📷 Image input with your own picture. In Shot · look + action, refer to them as image 1, image 2 and image 3 and describe one simple action. You can wire up to nine references.
- Check the editor estimate, then run with your NanoGPT key. Three Muse stills at $0.011 each + H3 Reference-to-Video at 540p for 5 s, reported $0.435 (the 540p rate of $0.075/s is $0.375; the rest matches about $0.02 per reference image). The saved run was $0.468. With your own reference pictures, skip the Muse stills.
- Check each reference in the clip: the character's face, clothes and colors, the prop's shape and color, and whether the setting matches the place still. Then check framing: here the model kept the hedgehog at the left edge and panned away instead of following the prompt.
Download workflow · Original sampled graph · Explore MCP tools · awesome-noodles