Talking photo
One photo with a story in its face + one short line → the photo performs it, mouth driven by the voice clip.
The script node carries a direction line plus the spoken line. A Gemini TTS voice (Algenib) performs it, a trim node caps the clip at five seconds, and LTX-2.5 Fast takes the photo and the audio as direct inputs — generated audio off — and moves the mouth to the supplied voice. GLM writes the guide: what you made, how it works, and the honest edges, including the per-second price and the pause caveat.
Saved result
Talking-photo guide · GLM writes what you made and the honest edges · reported $0.00
WHAT YOU MADE — This video is a still photograph of an ancient marble emperor, used as the photo's subject, performing one spoken line. The mouth movement is driven entirely by the voice clip, not generated speech. The line performed is: "Two thousand years silent... and you wake me NOW?" The emperor appears to speak these words directly, as if woken after two thousand years and not pleased about it. HOW IT WORKS — The script line was performed by a Gemini TTS voice, Algenib, delivering the old man's gravelly, clipped reading. The audio was trimmed to five seconds. LTX-2.5 Fast then took the photo and that audio as direct inputs, with generated audio turned off, so the clip carries only the original voice track. The clip's length follows the audio's length. Note that audio-driven runs render at 1080p even when 720p is selected. THE HONEST EDGES — Billing is per second: $0.14 a second at the audio-driven 1080p rate, so this five-second clip is about $0.70, plus a few cents for the speech. Keep lines to about ten words. No current model reliably closes the mouth on pauses; in a frame-counted shootout, LTX was best of the field and still closed the mouth on only 2 of 6 pauses. Short lines with few pauses forgive most. Front-facing faces with an unobstructed mouth work best, and statues and paintings forgive more than photographs of real people — which suits a marble emperor well.
References that went in
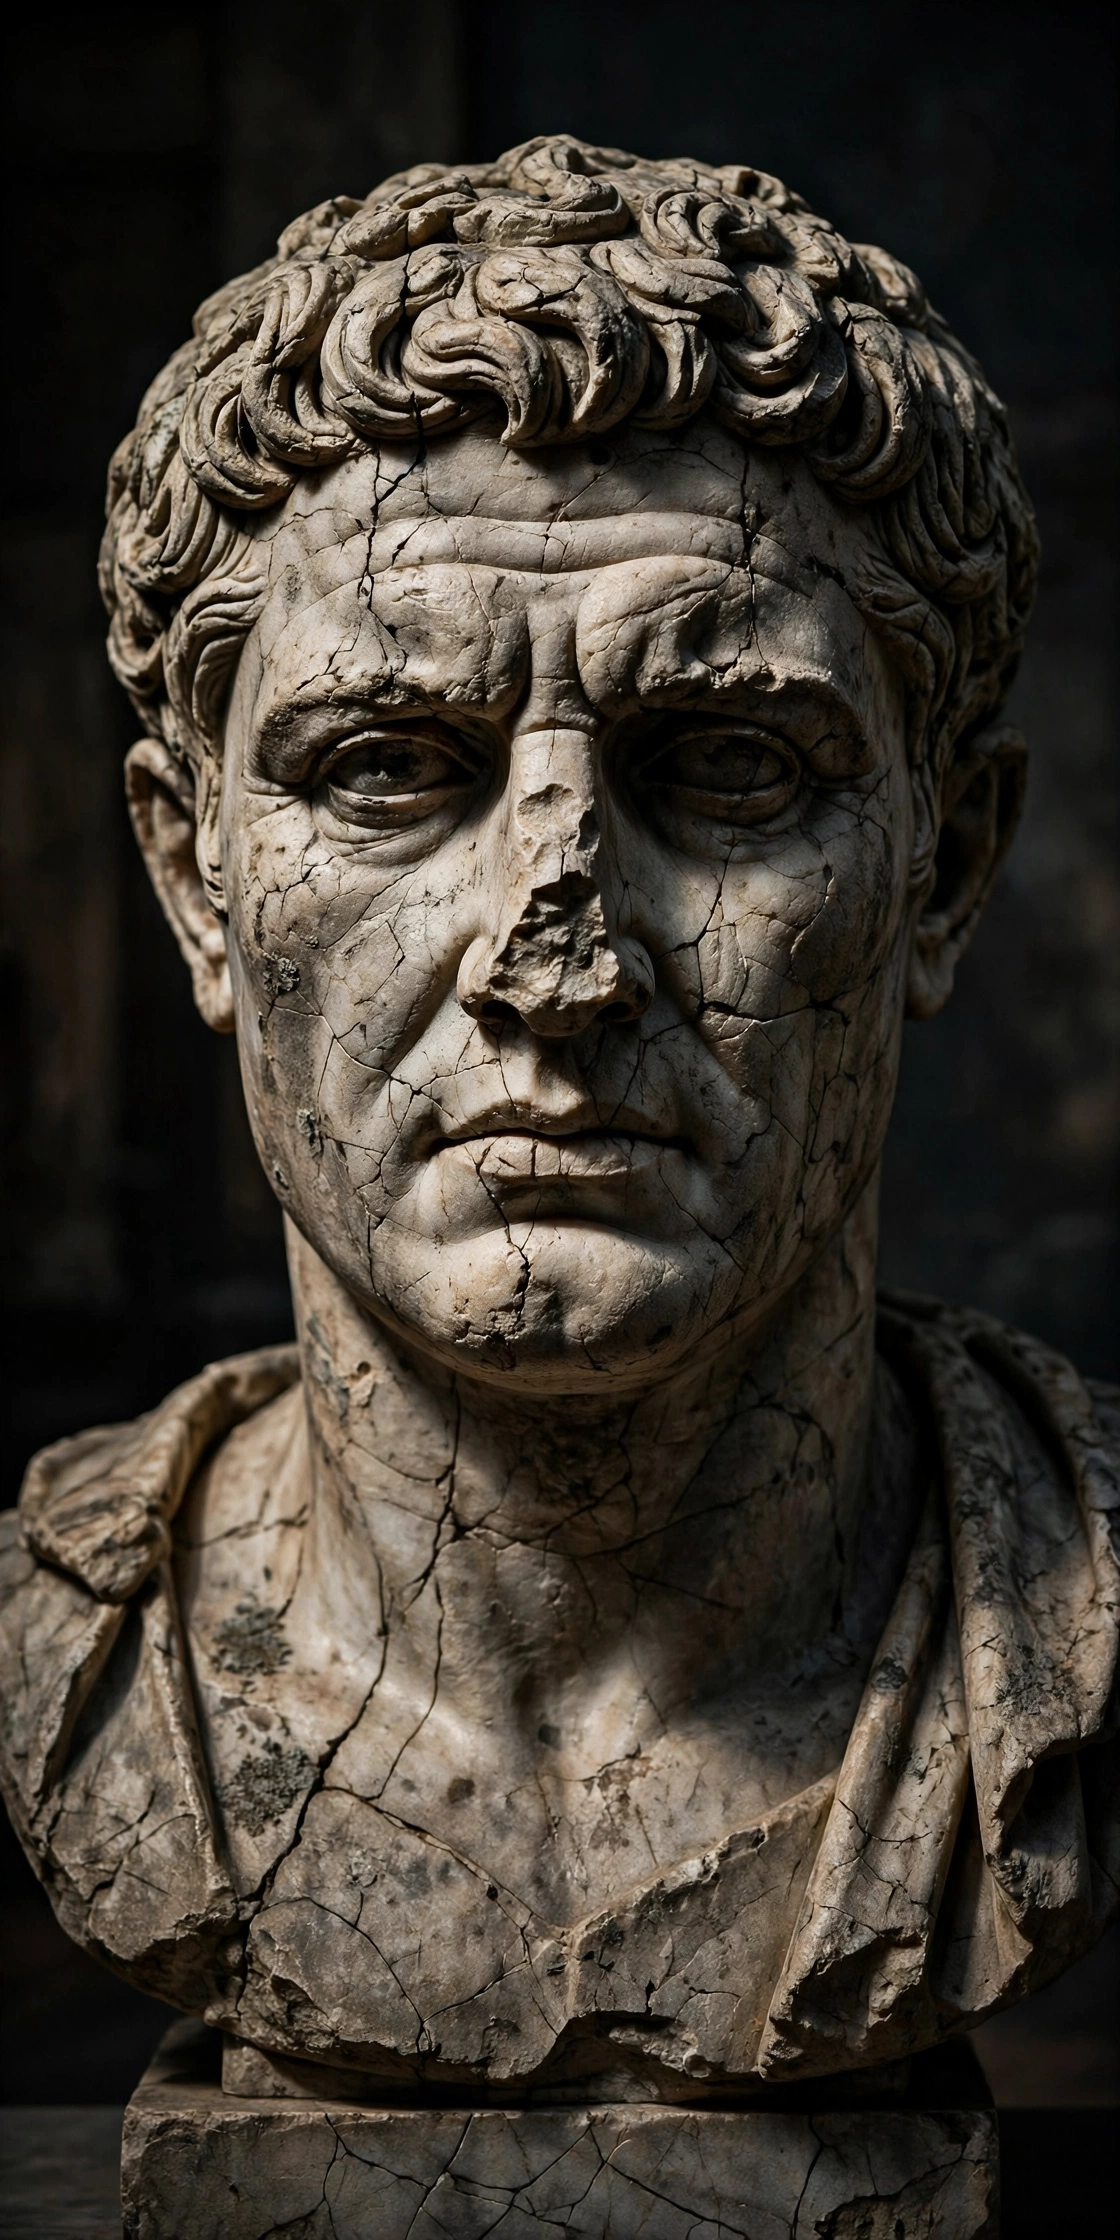
Upload one front-facing photo with a story in its face — a statue, a painting, a portrait — write one short line, and the photo performs it. The script node carries a direction line plus the line itself; a Gemini TTS voice (Algenib) performs it, a trim node caps the clip at five seconds, and LTX-2.5 Fast takes the photo and the audio as direct inputs, generated audio off, and moves the mouth to the supplied voice. A GLM guide closes with what you made, how it works, and the honest edges. The demo subject is a cracked marble emperor bust, chipped nose and all, delivering: "Two thousand years silent... and you wake me NOW?" The sync claim was checked in the video, not the listing: a probe run came first, and on this saved run the mouth was frame-checked against the audio — wide open mid-line (1.5s) and closed on the script's ellipsis pause (~3.0s), where the waveform itself goes quiet. The voice pairing was checked the same way: the example first shipped with Sulafat, a female voice (measured 210 Hz) on a marble emperor — caught and called out the same day — and was re-voiced with Algenib, whose performance here measures 143 Hz; the clip above is that corrected run. Two pricing facts the catalog listing does not shout, both measured: audio-driven LTX runs render at 1080p even when 720p is selected, so they bill at the 1080p rate of $0.14 a second, not the $0.10 720p rate — a 5.00s clip bills exactly $0.70 — this saved run billed $0.70, plus about $0.025 of speech and a $0 guide. The honest edges, also printed in the guide: no current model reliably closes the mouth on pauses — in a frame-counted shootout LTX was best of field and still only closed on 2 of 6 pauses — so short lines with few pauses forgive most (this demo's pause did close; do not count on it). Keep scripts near ten words, because every second bills. Front-facing faces with an unobstructed mouth work best, and statues and paintings forgive more than photographs of real people. Have your own voice clip? Replace the speech node with an audio upload wired into the same port.
Make it yours
- Open the graph — save first if the canvas already has your work. Undo brings yours back.
- Swap Subject photo for a front-facing photo with an unobstructed mouth — statues and paintings forgive more than photographs of real people. Rewrite Script — what the photo says: keep the direction line, change the words after Script:, and stay near ten words — the trim caps the voice at five seconds and every second bills. Keep Talking photo on
lightricks/ltx-2.5/fastwith generated audio off; your own recorded clip can replace the speech node, wired into the same audio port. - Check the editor estimate, then run with your NanoGPT key. Two paid calls: the saved run reported $0.70819 in total (LTX-2.5 Fast $0.6832 for 4.875 seconds at the audio-driven 1080p rate of $0.14/s, speech $0.02499 balance-verified, GLM guide $0.00). Prices and results vary.
- Play the saved clip and watch the mouth against the words: in the probe and the saved run it is nearly closed at the audio pause and wide open on the loudest word. Then read the guide's honest edges — no current model reliably closes the mouth on pauses, and audio-driven runs render at 1080p even when 720p is selected.
talking-photo.NOTE.txt
Download workflow · Original sampled graph · Explore MCP tools · awesome-noodles